
 LinkedIn
On dunedale.com, Claude-User fetched /robots.txt 1,218 times in 30 days from verified IP ranges, according to our 30-day crawler teardown. That is a better reason to open your server logs than another pitch about “technical issues hurting AI visibility.” Before you buy a tool, check whether ChatGPT, Claude and Perplexity can reach the pages you want them to read.
I ignored logs for years. I lived in the search terms report and treated access logs as hosting support’s problem. I was wrong. Logs show the request, the page, the response and the claimed User-Agent. They also show something a dashboard count can hide: anyone can claim to be an AI bot. Your job is to separate verified requests from costumes, then find the requests that failed.
At the end of this hour, you will have a list of verified AI requests by page and status, plus a short list of access problems to fix. You need 30 days of raw access logs, a terminal or text editor, and read access to robots.txt and your CDN firewall settings. If your CDN handles requests before they reach your server, you need its logs too. No paid tool. No new tag.
Step 1: Export 30 days of requests, not a dashboard summary
Pull the line-by-line access log for the last 30 days. The menu depends on your stack:
- cPanel:
Metrics > Raw Access - Plesk:
Logs - Your own server:
/var/log/nginx/access.logor/var/log/apache2/access.log - Cloudflare:
Analytics & Logs
Requests blocked at the CDN do not appear in your origin log. Check both sources before declaring a bot absent. Export each domain separately, keep the originals untouched and work on copies.
Expected result: a .log or .gz export containing an IP address, timestamp, requested path, HTTP status and User-Agent for each request. Open the first 20 lines. If you cannot find User-Agent strings, you have the wrong report or a log format that needs changing before the next measurement period.
Common mistake: exporting seven days and treating a quiet week as proof that nobody visits. Requests can arrive in bursts. Use the full 30 days for the first pass; later, compare equal periods from the same log source.
Step 2: Filter for AI bot names, then read the status
In the directory containing your copied origin logs, run a substring match. User-Agent strings can carry extra text, so an exact-string match is too brittle. Change access.log* if your files have different names.
zgrep -iE 'GPTBot|OAI-SearchBot|ChatGPT-User|ClaudeBot|Claude-User|Claude-SearchBot|PerplexityBot|Perplexity-User' access.log* > ai-hits.log
Open ai-hits.log. Read the bot name, requested path and status together. A 200 says the server returned a successful response; it does not prove the page contained useful text. A 403 or 429 points to a denial or rate limit. A 301 calls for another look at the redirect destination, not an automatic verdict that the page is blocked. Status and URL together tell you more than a bot count.
Keep three working categories in mind as you scan:
- Training crawlers:
GPTBotandClaudeBot - Search crawlers:
OAI-SearchBotandClaude-SearchBot - User-triggered fetchers:
ChatGPT-User,Claude-UserandPerplexity-User
PerplexityBot is also worth tracking, but do not label every one of its requests a user-triggered fetch. The categories help you distinguish model training, search discovery and a page requested around an answer. They are not proof that a particular visit produced a citation. The agents have different jobs, and the logs show requests, not the finished answer.
Make a quick tally by bot, path and status. If your file uses the common combined access-log layout, where the path is field 7 and the status is field 9, start with:
awk '{print $9, $7}' ai-hits.log | sort | uniq -c | sort -rn | head -30
Check those field positions against a few original lines first. CDN exports can use different layouts; do not run this command on a different format and trust its output. Also, do not hunt for Google-Extended in the access log. It is a robots.txt control, not a separate HTTP User-Agent.
Expected result: a manageable list of claimed AI requests and the pages they asked for. Common mistake: calling this list “verified AI traffic.” It is only a list of names supplied in request headers. Verify the IPs next.
Step 3: Check IP ranges before you count a bot
Anyone can send User-Agent: GPTBot. I filter first and verify second; otherwise, a scraper in a bot costume can make an account look busier than it is. One demonstration found three spoofed hits among 15. That example is a warning about the method, not an estimate for your site.
For a log with the client IP in its first field, extract the addresses:
awk '{print $1}' ai-hits.log | sort -u > suspect-ips.txt
Check the first field before using the file. A CDN or proxy can change which address your origin records. If that field is the proxy rather than the requester, use the appropriate client-IP field from your export instead.
Now take one claimed bot at a time. Get its published IP ranges from the matching vendor list, including OpenAI’s bot-specific lists or Anthropic’s published ranges. Put the relevant CIDR prefixes in vendor-prefixes.txt, one per line. Do not mix vendors’ ranges and then treat any match as proof of the User-Agent’s identity. Run this check:
python3 - <<'PY'
import ipaddress
from pathlib import Path

ranges = [
    ipaddress.ip_network(line.strip(), strict=False)
    for line in Path('vendor-prefixes.txt').read_text().splitlines()
    if line.strip() and not line.lstrip().startswith('#')
]

for line in Path('suspect-ips.txt').read_text().splitlines():
    try:
        address = ipaddress.ip_address(line.strip())
    except ValueError:
        continue
    result = 'in range' if any(address in network for network in ranges) else 'unverified'
    print(f'{address}\t{result}')
PY
Match each in range address back to the lines in ai-hits.log that claim the corresponding bot. Repeat with the next bot’s published ranges. A reverse lookup can be a useful spot-check, but a hostname alone is not your count. Keep the unmatched lines as unverified, not as verified bot activity.
Expected result: a defensible set of requests to tally by bot, path and status. Common mistake: checking an IP against some AI vendor’s ranges while reporting it as the bot named in its User-Agent. Match the vendor and the claimed bot before it enters your verified column.
Step 4: Use one site’s numbers to choose what to inspect
Here is why the IP check matters. In our 30-day dunedale.com teardown, /robots.txt had 13,319 raw hits carrying AI bot tokens. The reported verified count was 3,806. Within that page’s activity, Claude-User alone accounted for 1,218 verified fetches. Those figures describe requests to one file on one site, not an industry-wide spoofing rate or a count of citations.
| Page in the 30-day teardown | Reported verified hits | Reported user-triggered fetches | What I check next |
|---|---|---|---|
/robots.txt | 3,806 | 1,218 Claude-User | Whether permission checks lead to successful page requests |
Homepage / | 900+ | 802 ChatGPT-User | What text the homepage returns |
| Category and service pages | Hundreds | 0 reported live-answer pulls | Whether those pages are reachable and readable |
The homepage count is a useful lead, not evidence that ChatGPT cited the homepage 802 times. Likewise, zero reported user-triggered pulls on category and service pages does not prove the content is poor. It might mean no matching request arose in that period. The data runs out at the request log.
The decision: inspect access and returned HTML before rewriting a page. If the page cannot be fetched, copy changes will not fix delivery. If it can be fetched and requests still do not appear, you have learned something narrower: access is not the blocker you found in these logs.
Step 5: Find the block at robots.txt, the CDN or the page
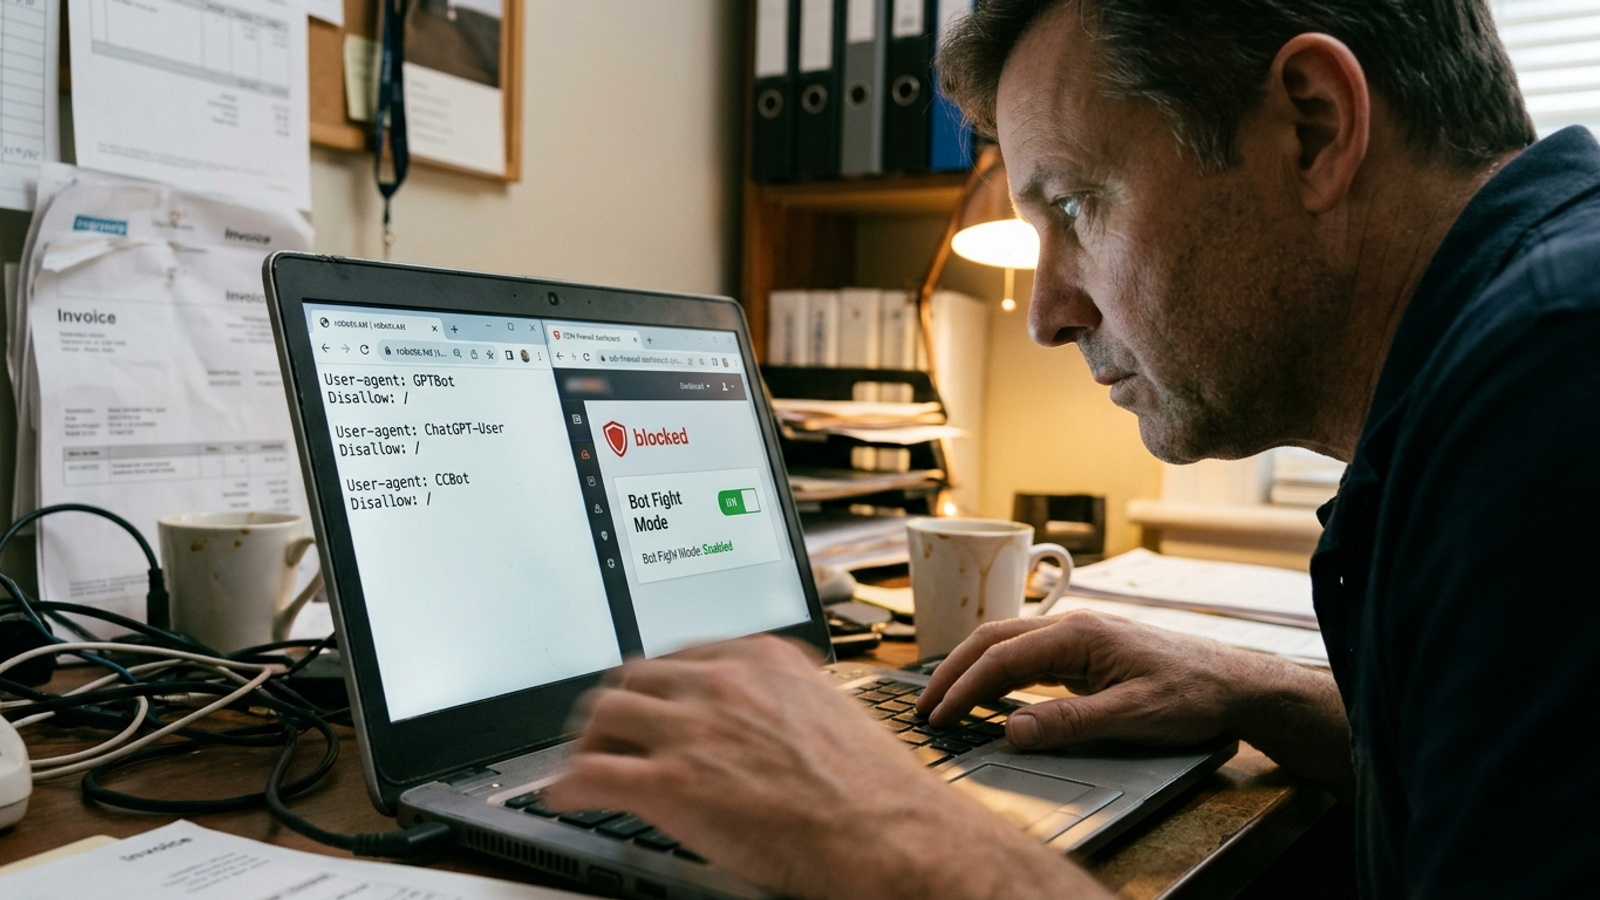
Open https://yoursite.com/robots.txt beside your CDN firewall settings. Look for User-agent: * with Disallow: /, or disallow rules covering a key /shop/, /blog/ or pricing path. Read the bot-specific groups too; do not infer the rule for every agent from one line. If access for a search crawler is blocked, that can affect its ability to discover pages for ChatGPT search.
In Cloudflare, check Security > Bots for Bot Fight Mode or Block AI Bots. If a rule appears to catch the requests you care about, test a narrowly chosen path rather than switching off protection everywhere. The log tells you whether the response came from the CDN or made it to origin; an origin log alone cannot diagnose a request it never received. robots.txt and the firewall are separate checks.
Return to the non-200 lines in your verified set. Look for 403s, 429s and redirects on pages you want assistants to read. Trace a redirect to its final response; a 301 is not a failure by itself. If you need a fuller pass on the access controls, use the AI crawler swipe file after you have named the blocker.
Then inspect what your server actually returns for a key page. This command follows redirects, prints the final status, saves response headers and writes the HTML to page.html:
curl -sS -L -A 'ChatGPT-User' -D headers.txt -o page.html -w '%{http_code}\n' https://yoursite.com/key-page/
head -c 2000 page.html
Look for the page’s headline and a plain-language answer in the returned HTML, not just a JavaScript shell or challenge page. A request made with a bot User-Agent is not proof that the real bot’s IP can get through; confirm that with your verified logs. Major agents examined in this context read returned HTML rather than executing page JavaScript. The curl and CDN audit goes deeper on an empty response.
Expected result: you can name the failing layer: permission rule, firewall response, rate limit, redirect destination or missing HTML content. Common mistake: editing copy while the fetcher still receives a challenge page. Fix delivery first.
Step 6: Fix the specific failure and redeploy
If robots.txt blocks the agents you want to admit, edit the relevant groups. If your choice is to block the listed training bots while allowing the listed search and user-requested agents, start with this example and adjust it to your policy and paths:
User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: OAI-SearchBot
Allow: /

User-agent: ChatGPT-User
Allow: /

User-agent: Claude-User
Allow: /

User-agent: PerplexityBot
Allow: /
Do not paste that file without checking the rest of your existing rules. In particular, OpenAI says robots.txt rules may not apply to a user-triggered ChatGPT-User fetch. Your verified responses remain the better test of whether requests get through.
If the failure sits at the CDN, change the rule for the affected path and agent instead. If delivery works but page.html is an empty shell, put a 40- to 60-word answer block in returned HTML near the top of the key template. State what the offering costs, who it fits and how long it takes where those answers belong on the page. Do not leave that text behind a client-only fetch. Add key pages to sitemap.xml and submit it in Search Console if they are missing.
Expected result: your test URL returns a successful response containing the answer text, and subsequent verified requests no longer show the access failure you fixed. Common mistake: changing robots.txt while a firewall rule still drops the request first. Redeploy, then check both layers.
Step 7: Verify the fix after seven full days
Export the next seven days from the same sources and run the same filter, IP-range check and status-by-path tally. Rename the output so you do not overwrite the first pass:
zgrep -iE 'GPTBot|OAI-SearchBot|ChatGPT-User|ClaudeBot|Claude-User|Claude-SearchBot|PerplexityBot|Perplexity-User' access.log* > ai-hits-week2.log
awk '{print $9, $7}' ai-hits-week2.log | sort | uniq -c | sort -rn | head -30
As before, the awk command assumes the common combined-log field positions. Verify IPs before comparing bot counts, and compare equal-length periods if you want a count to mean anything. A delivery fix is visible when a previously denied, verified request to a key path receives a successful response. A new user-triggered fetch to that page is useful evidence of activity, but you cannot schedule one: it depends on someone making a relevant request.
Expected result: you can show which blocked paths changed status and whether the returned HTML contains the answer. Common mistake: checking after 24 hours, seeing no new user-triggered fetch and calling the fix a failure. Give the requests time to arrive. If statuses improve but those fetches stay at zero, report exactly that; the logs do not tell you whether demand, discovery or the page’s content explains it.
Before you close the laptop, check three things in the second export and your saved HTML: verified successful responses on the homepage and a key money page, no remaining 403s for the agents and paths you meant to admit, and answer text present in the returned page. If a money page also gets its first verified user-triggered fetch, record it. Do not manufacture one as a success criterion.
I used to tell clients to buy the audit tool first. I was wrong. Read the logs, fix the fetch, then change the page: if access is clean and the page still gives a thin answer, make that answer worth quoting. Only then decide whether the ongoing work is yours to run or worth handing to groas and its named strategist.