
 LinkedIn
Most agencies will sell you a screenshot. They run your best prompt once in ChatGPT, catch your name in the answer, and call that visibility. I used to treat an early ad-copy result the same way: one impression, one click, big conclusion. I was wrong. Run the same prompt again and you may get a different answer.
Thinking Machines Lab sampled the same prompt 1,000 times at temperature zero and got 80 different completions. The most common appeared only 78 times. Add live retrieval, location, memory and silent model updates, and the question becomes a PPC testing question: Does my brand appear often enough, under controlled conditions, for a change to mean anything?
This protocol uses a fixed prompt set, repeated runs per engine, a mention rate with its spread, and a group of pages you leave alone. Set the test up first. Then look at the answer.
Setup: freeze the prompts before you see a score
Build your set from buyer questions, not phrases you wish buyers typed. Pull 30 prompts from Search Console queries, sales call notes and the comparison questions prospects actually ask. Split them roughly into thirds:
- Problem prompts: best way to fix emergency leak without replacing boiler
- Comparison prompts: brand A vs brand B for 50-person team
- Buying prompts: how much does X cost for a 3-bed house
That mix matters. Head terms tend to pull from a small pool of high-authority pages; long-tail questions leave smaller brands more room. Write all 30 from memory around your strongest product and you have tilted the result before the first run, as practitioners tracking score accuracy warn.
Thirty beats 300 if 30 is the set you will actually run again under the same conditions. Label it v1.0 with a date and freeze the wording. Separate branded from unbranded prompts, and keep branded prompts out of the headline rate. Of course ChatGPT names you when someone types your name. That is recall, not evidence that a buyer will find you without asking for you.
If you need a starting sheet, use the 30-prompt test for AI search visibility. Once you lock your set, resist the temptation to improve it mid-test. Add five prompts and drop three next month, and the old and new scores no longer describe the same questions. A prompt change is a new test version, not a visibility lift.
Keep each engine in its own lane
Run the set in ChatGPT, Gemini and Google AI Overviews. Report each engine separately. Across 383,188 citations for 64 ecommerce brands, AI Overviews and Gemini shared just 15.8% median domain overlap; only 2 of the 64 brands shared the same number one source. Overviews cited social content 7.5 times more often, while Gemini leaned on editorial pages 1.7 times more.
I treat them like Search and YouTube in 2016. Same company, different inventory. If one engine starts citing your page and another never names you, a blended average hides the useful part. The engine is part of the result. Keep its name attached to every row you log.
Hold the conditions still enough to compare runs
The controls are boring. They also decide whether next month’s sheet means anything:
- Start a fresh chat for every prompt. Do not ask follow-ups in the same thread.
- Stay logged out or use a clean profile with memory off. Keep the declared location and language the same.
- Record the model version, date and time. Run the whole set inside a few hours rather than stretching it across two weeks.
- Repeat those conditions when you run the set again.
Those are the conditions teams use for defensible measurement: cold-start chats, account isolation, a declared region and model version, and a tight window. Skip them and your week-over-week delta may be a location change wearing a costume. You cannot freeze an engine’s retrieval index, but you can stop changing your own setup between runs.
Log rivals as a baseline, not as the page holdout
Choose two or three named rivals and record whether each appears on every prompt, every run. This is your rival baseline for the program. If your mention rate rises from 20% to 35% and theirs rises in the same period, do not credit your page edit yet. If yours moves while theirs sits flat, you have a more interesting result to inspect.
Use the same share-of-voice and citation-rate distinctions for every brand. Count appearances and citations against the same frozen set, then report the rates per engine. Do not compare your unbranded rate with a rival’s rate from a different batch of prompts. That is not a contest; it is two spreadsheets avoiding eye contact.
Rivals help you spot a wider engine shift. They are not the holdout for a content edit. For that, you need pages of your own that remain untouched. No rival baseline, no confident story about a lift; no untouched pages, no clean test of the edit.
Measurement: count runs, save answers, report the spread
Run every prompt three times per engine. That repeated-run design follows practitioner guidance on score accuracy: freeze the set, repeat each prompt at least three times per period, report per engine and retain rivals as a baseline. One vendor describes 12 runs per prompt across four engines, or three per engine. More sampling steadies the reading; it does not remove model, geography or time effects.
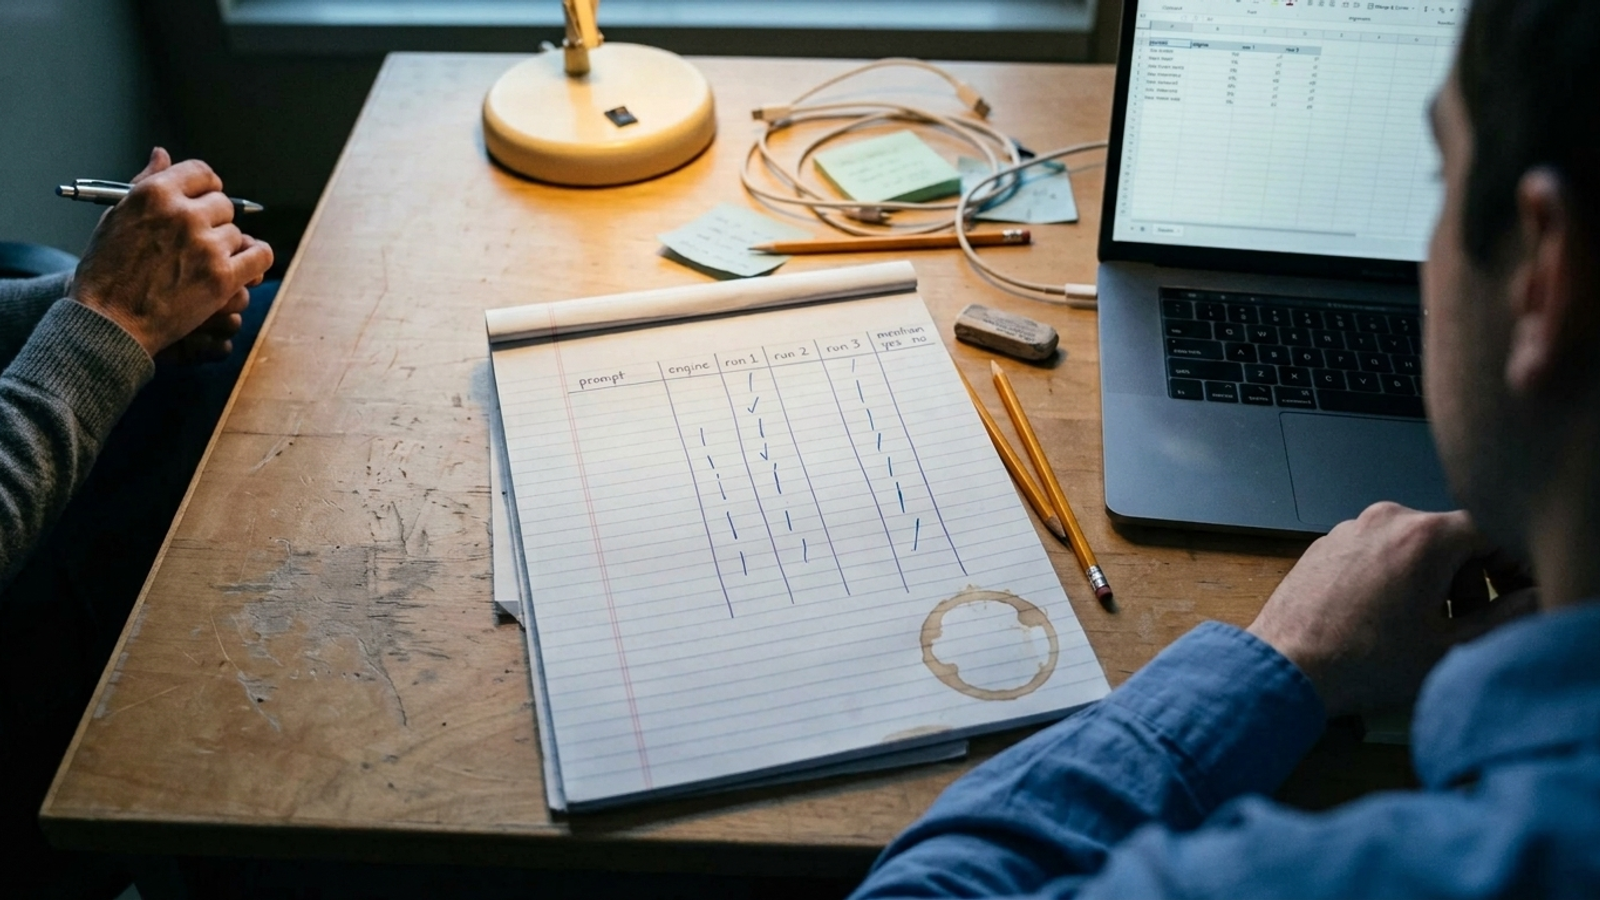
Make each run a row. For that row, log:
- Mention: yes or no, including the brands of any rivals that appear.
- Citation: whether the engine links to your page or only names you, with the URL if there is one.
- Prominence: whether you appear in the lead paragraph, mid-answer or buried in a list.
- Record: the raw answer, engine, prompt version and timestamp.
Then calculate the mention rate from runs, not from memorable screenshots: runs that mention the brand divided by all runs for that engine and prompt set. Do the same for linked citations and for each rival. Show the individual prompt results beside the overall rate so a reader can see whether a change is widespread or comes from one question flipping between answers. If a prompt names you once in three runs, log that spread. Do not turn it into a firm yes.
The named-versus-cited distinction matters for revenue work. An answer can put your brand in a list without linking to you. A cited page gives the reader a source to visit. Track both, but report citation rate separately from mention rate. Otherwise a pile of unlinked mentions can look like progress even when there is no corresponding route to your site.
If you need a place to put the rows, build an AI visibility tracker that measures mention rates, not screenshots offers a sheet layout to start from. Save the outputs as well as the scores. When a rate changes, you will want to read what the engine actually said, not argue over a cell filled in last month.
For a quick qualitative pass, use the 0-to-2 rubric for frequency, prominence, citation quality and sentiment, plus coverage breadth. Its baseline runs over 25 to 40 prompts across four themes, with raw outputs, links and timestamps saved for retesting. I would keep the working labels plain:
- Mention: 0 for absent, 1 for named in passing, 2 for recommended as an option.
- Citation: linked source URL, or 0 when you are named with no link.
- Prominence: lead paragraph, mid-answer or buried in position six of seven.
- Rival check: which of your named rivals appeared in the same answer.
Use the labels to decide what to inspect. Use the run counts for the rates. A neat score is not a substitute for the answers behind it.
Reading the result: a 15-point jump may still be noise
Small prompt sets make tidy-looking percentages out of messy evidence. At a 20% appearance rate with 20 prompts, the error band is plus or minus 17.5 points. At 50 prompts it tightens to plus or minus 11.1; at 100, to plus or minus 7.8. Comparing 20% with 25% at n=50 carries around 16 points of error on the difference because small sets have wide error bars.
That is the mechanism behind the rule: a 30-prompt set run three times per engine is a baseline with a spread, not a verdict. A five-point move would need around 1,100 prompts per period to call it real with 80% power; a ten-point move needs around 290. You probably will not run that many. Neither will I. Report the rate, show how prompts varied across their repeated runs, and look for a gap that persists across repeated periods while rivals remain flat.
You can act sooner on a pattern than on a grand claim of lift. Sort prompts into those that mention you reliably, those that sometimes mention you and those that do not. Do this per engine. If comparison prompts name incumbents while long-tail problem prompts cite forums, publishers or a help document answering the exact follow-up, the next task is visible in the raw answers.
Do not rewrite a page that already gets cited just to make the headline number move. Find the cluster where you are absent across all three runs while rivals appear. Map those prompts to the pages that should answer them. The useful objective is specific: move a cluster from zero mentions in its repeated runs toward being cited consistently. Whether an edit caused that movement is the next test.
The holdout test: did the page edit cause the change?
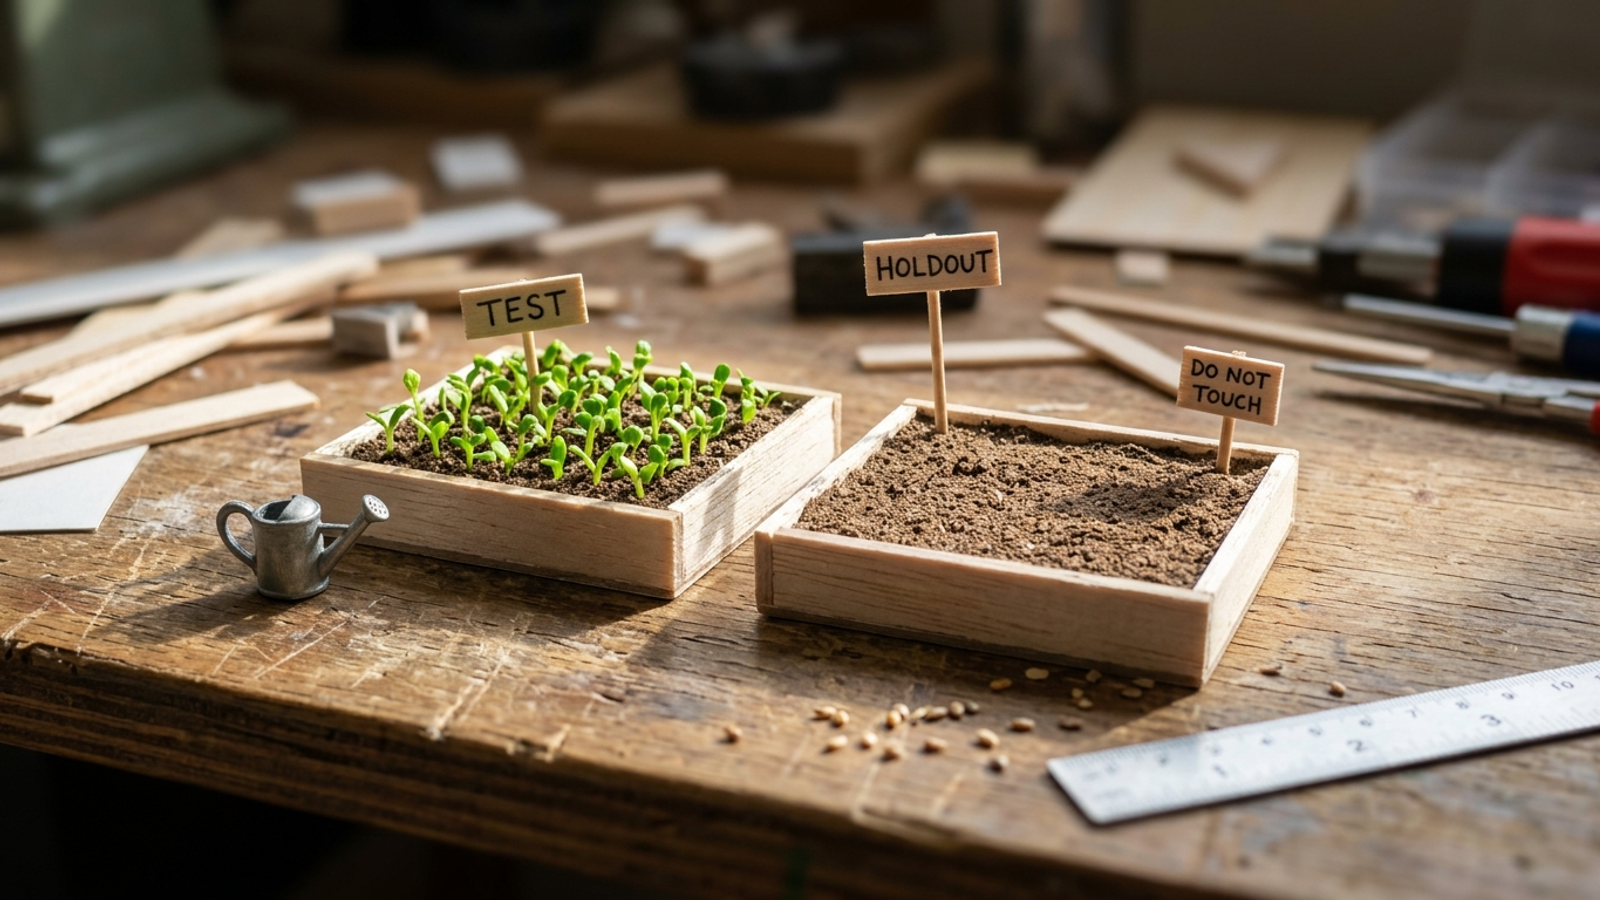
Choose test pages and matched holdout pages before you edit anything. Take six to eight pages mapped to prompts where you are absent, then pair each with a similar page you will leave alone. Match on template, age and traffic band. Record which prompts map to each group. If you decide which pages count as the control after you see the results, you have given yourself room to pick a flattering story.
Change the test group. Freeze the holdout group. That is the logic of a marketing holdout test: withhold the treatment from a matched control and compare what happened to both. A before-and-after chart without that second group can show a change. It cannot, by itself, tell you what caused it.
Make one kind of edit in the test group: a direct answer block at the top, a cleaner facts table, or a citation-worthy stat with a date. Not all three at once. Re-run the same frozen prompt set three times per engine under the same conditions and compare the test-page citation change with the holdout-page citation change. Keep the rival baseline alongside both. You are looking for a gap that belongs to the edited pages, not a rising tide across the sheet.
Suppose test pages go from cited in 1 of 9 runs to cited in 6 of 9, while matched holdouts and rivals sit flat. That is a reason to keep testing the edit, not a license to declare causation from nine runs. If both page groups move together, an engine or retrieval change is a better explanation than your edit. The pairing approach is laid out in the AI citation holdout test.
Write down what would change your mind before you run the follow-up. Otherwise every result becomes proof that the work you already did was brilliant. Convenient. Not especially useful.
Limits: know when to wait, and when to skip the test
A clean protocol cannot stop silent model updates or shifts in retrieval. Teams measuring this more closely add 5 to 9 runs per prompt, report the spread, keep the measurement window tight and stamp each run with model version, region, language and time. They also put GA4 AI referrals from ChatGPT, Gemini and Perplexity next to the sampled visibility score. Repeated answers tell you whether you appear. Referral logs tell you whether visits follow. Neither should be passed off as the other.
Skip this protocol for now if you have no buyer prompt cluster, if your site is under three months old with nothing indexed to cite, or if what you want is a daily score for Slack. This is built to inform a monthly decision, not supply a daily dopamine hit.
Then let the outcome dictate the next move:
- If buying prompts return zero mentions across repeated runs while the same rivals keep appearing, work on the mapped content cluster and test it against untouched pages.
- If citations rise but AI referrals and branded search lift stay flat, inspect the answers. Being named is not the same as giving someone a reason to visit.
- If edited and holdout pages move together, leave the claim of lift alone. Re-run the set before changing more pages.
I can run this by hand for an account audit. For continuous tracking without the 1am spreadsheet work, groas tracks visibility across engines with a rival baseline built in. Either way, the rule stays the same: no fixed set, no repeated runs, no holdout, no claim that the edit lifted visibility.